From Pilot to Production: A Practical Playbook for Building AI Agents
How to pick the right first use case, build agents that work on real data and prove ROI in weeks, not quarters.
- Published
- Reading time
- 14 minutes
- Prepared by
- NPLUS Global Research
01 · Executive summary
Key findings
- 1Most AI pilots stall because they start with the technology, not with a repeated, measurable piece of work.
- 2The best first agents handle high-volume, rules-heavy tasks where a person can check the output quickly.
- 3Data access and evaluation take more effort than the model itself; plan for them from day one.
- 4Agents that keep a human in the loop at the start reach full automation faster, because trust is earned with evidence.
02
Why so many AI pilots never reach production
Building an impressive demo takes an afternoon. Building an agent that works every day on messy real data, inside your security rules, with results you can measure, is a different job. Pilots stall for the same few reasons: no clear owner, no baseline to compare against, no access to the right data, and no way to tell whether the agent is getting better or worse.
The fix is to treat an agent like any other product: a defined job, a measurable outcome, a test suite and a release plan.
03
Selecting the first use case
High volume
The task happens dozens or hundreds of times a week, so small time savings add up fast.
Clear rules
A good employee could write down how it is done. If nobody agrees on the right answer, an agent will not either.
Easy to check
A person can verify the output in seconds, which makes human review cheap while trust builds.
Low blast radius
Mistakes are reversible. Start with drafting, triage and data entry before payments or customer commitments.
Good first candidates
Support ticket triage and draft replies, invoice and document extraction, CRM data entry and enrichment, lead qualification, internal knowledge Q&A, and report preparation.
04
The architecture of a production agent
Model layer
Pick the model per task. Use the most capable model for reasoning-heavy steps and smaller, cheaper models for classification and extraction.
Knowledge layer
Retrieval (RAG) over your approved documents, with permissions respected, so answers are grounded in your facts, not the internet.
Tool layer
Narrow, well-described tools for each system the agent uses, each with its own permission scope and rate limits.
Orchestration
Clear steps, retries, timeouts and hand-offs to a human when confidence is low or the action is high-impact.
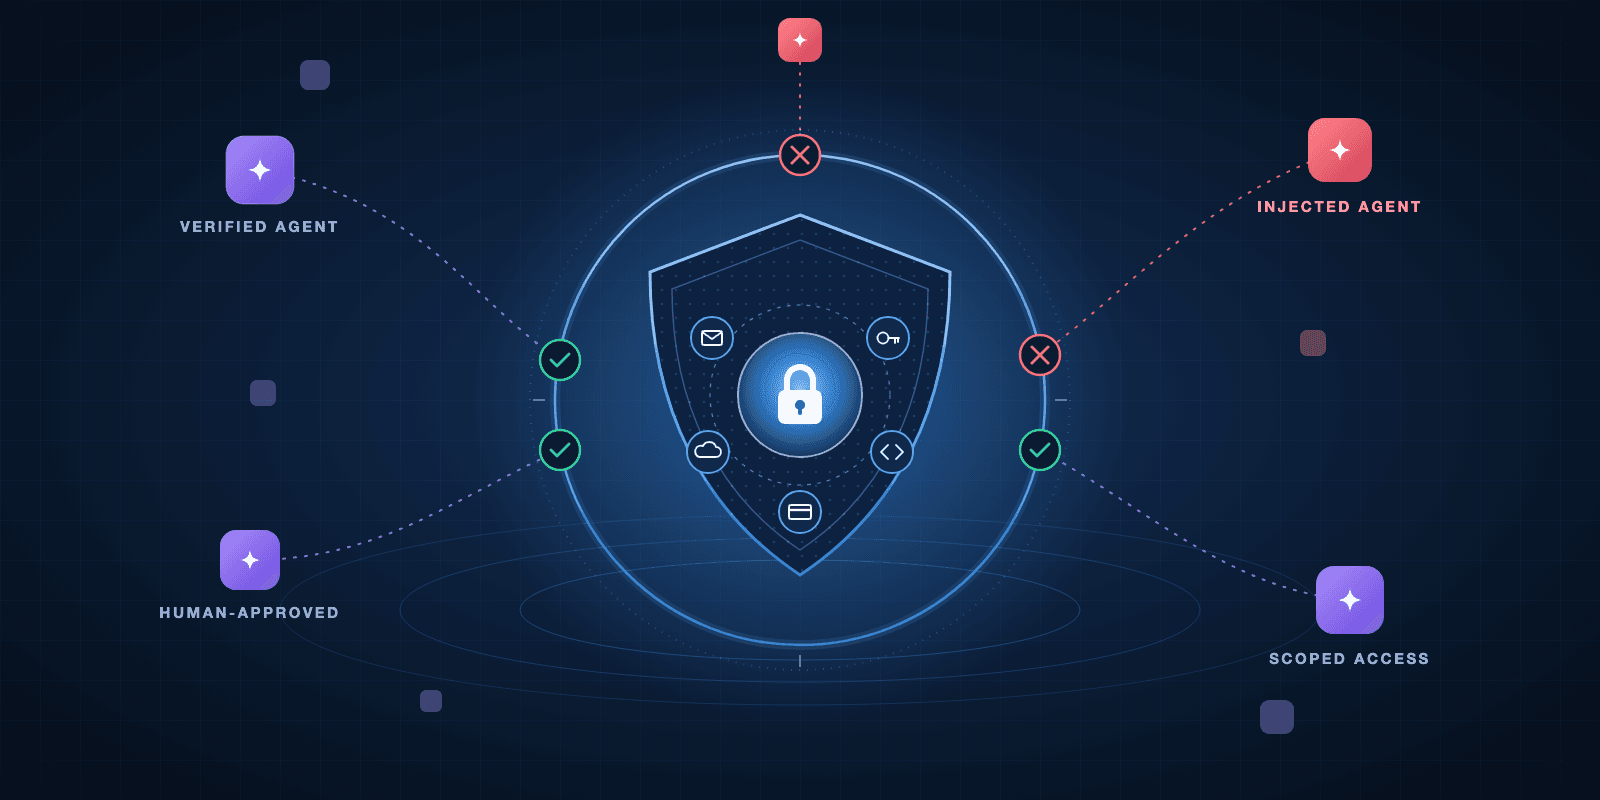
Guardrails and logging
Input and output checks, sensitive-data filters, and a full trace of every step for debugging and audit.
05
Data readiness
Agents are only as good as the data and systems they can reach. Before building, confirm three things: the agent can access the data it needs through an API or export, that data is current and reasonably clean, and access respects the same permissions a human would have.
Budget time to fix duplicate CRM records, outdated documents and missing fields. Cleaning this up pays off twice: the agent works better, and so do the humans.
06
Evaluation and quality assurance
Build a test set
Collect 50 to 200 real examples with known correct answers before you write a prompt. This is your scoreboard.
Measure what matters
Accuracy, time saved per task, escalation rate, cost per task and user satisfaction, compared with the human baseline.
Test the edges
Include unusual, incomplete and adversarial inputs, including prompt-injection attempts.
Re-run on every change
Any new prompt, model or tool must pass the test set before release, just like software regression tests.
07
Phased rollout
Shadow mode
The agent works alongside the team and its output is compared, but nothing is sent or saved automatically.
Assisted mode
The agent drafts and a person approves with one click. Track the approval rate and the edits people make.
Autonomous for proven tasks
Once accuracy holds above your threshold for several weeks, let the agent act alone on low-risk cases and keep humans on the rest.
08
Measuring return on investment
Report value in the language leadership already uses: hours returned to the team, faster response or cycle times, fewer errors, more capacity without new hires, and cost per task. Compare against the baseline you captured before launch.
Then reinvest. The second and third agents are faster and cheaper to build because the data connections, guardrails and evaluation tools already exist.
09 · Readiness checklist
Where does your organization stand?
- One owner and one measurable outcome per agent
- A baseline of today's time, cost and error rate
- A test set of real examples with correct answers
- Least-privilege access to only the data and tools needed
- Shadow, assisted, then autonomous rollout
- Monthly report on value, accuracy and cost
Fewer than four checked? NPLUS Global can run a short assessment and give you a prioritized plan.
10
References
- OWASP Top 10 for Large Language Model Applications, 2025 edition
- NIST, Artificial Intelligence Risk Management Framework (AI RMF 1.0), January 2023
- NPLUS Global delivery practice: AI agent implementation methodology
About NPLUS Global
NPLUS Global is a technology services company providing cybersecurity and compliance, AI agents and automation, and MarTech services to businesses in the United States and India. Contact info@nplusglobal.com or +1 (201) 279-0779.
This paper is provided for general information and does not constitute legal advice. Incident details are drawn from the public sources listed above. © 2026 NPLUS Global.